Teaching
A growing collection of interactive, in-browser demos that visualize core neural-network concepts — from a single neuron's forward pass to backpropagation and computation graphs. Drag the sliders, step through, and watch the math move.
These widgets are used in DSAI4207 to accompany the lecture on tokenization, embeddings, and data representation. Each card below opens a standalone demo page — click Open Demo to explore it.
 ▶ Interactive
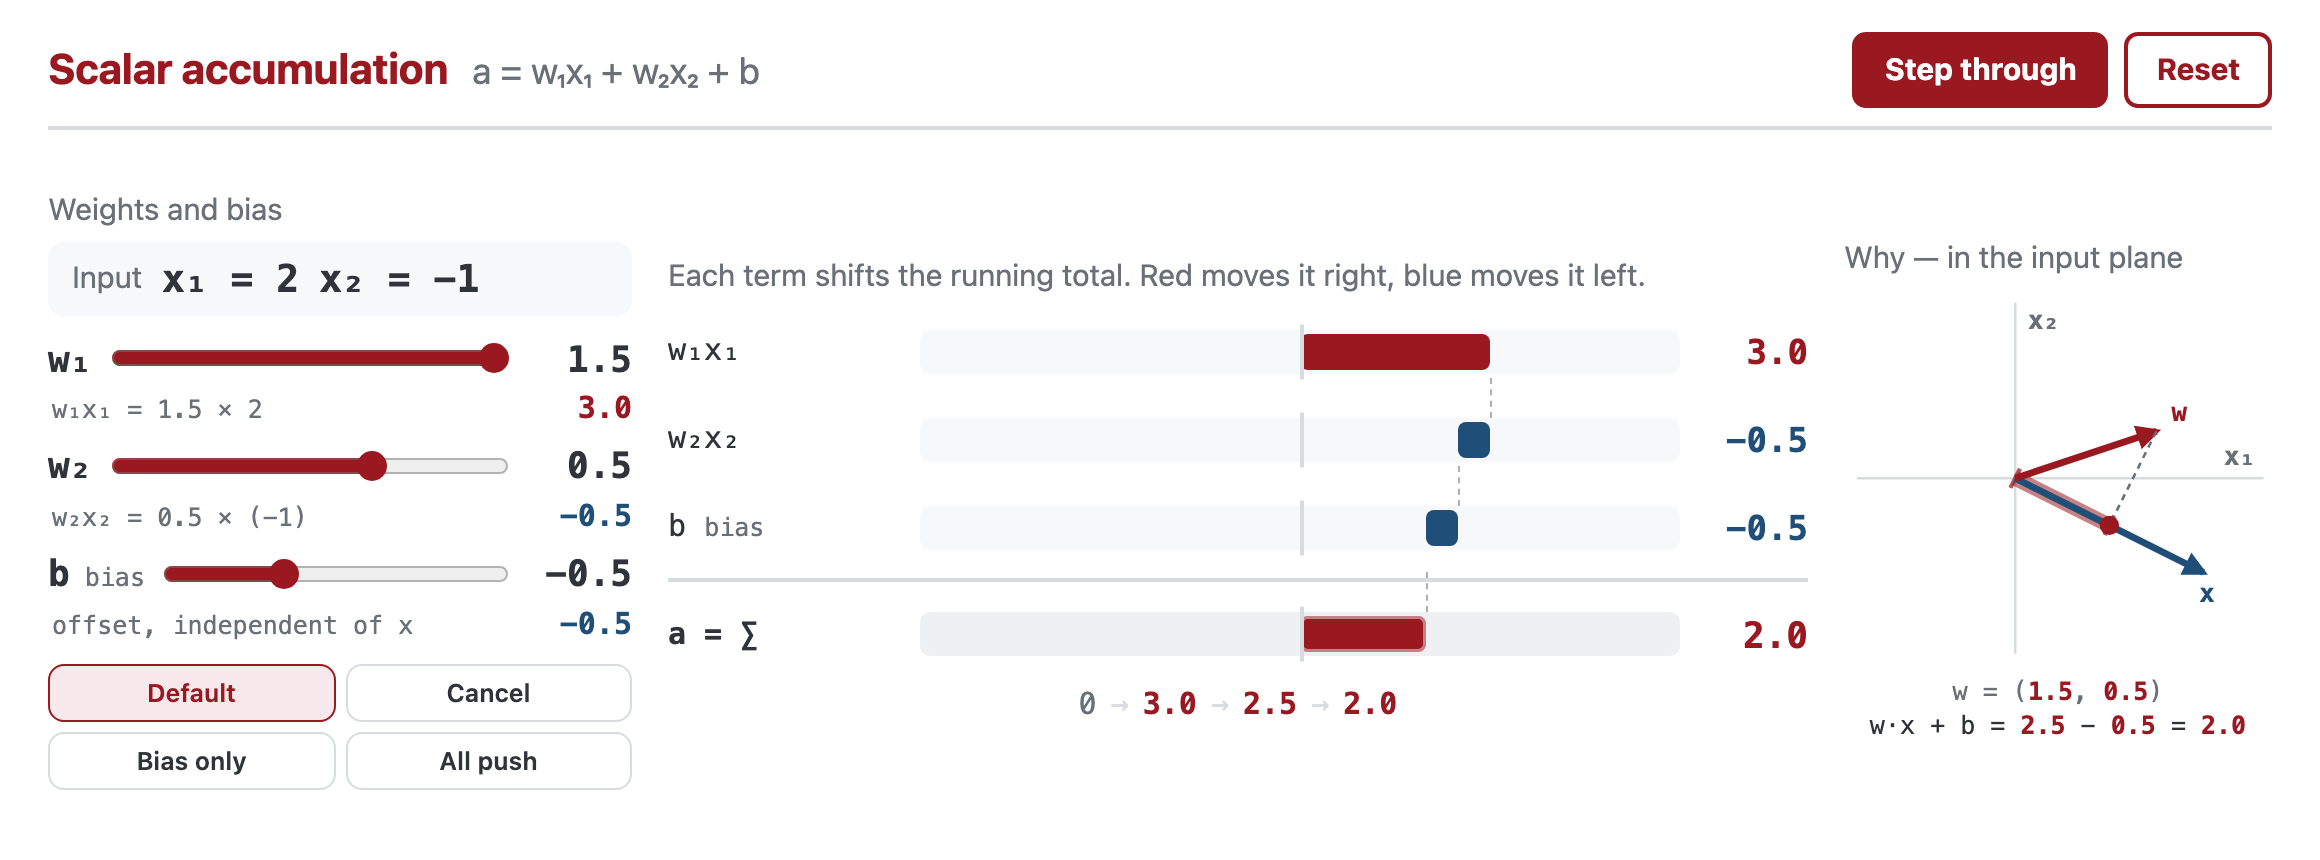
Scalar Accumulation
Step through a single neuron's forward pass, term by term: a = w₁x₁ + w₂x₂ + b, with a linked geometric view.
Knowledge point: weighted sums and the bias term inside a neuron.
Open Demo →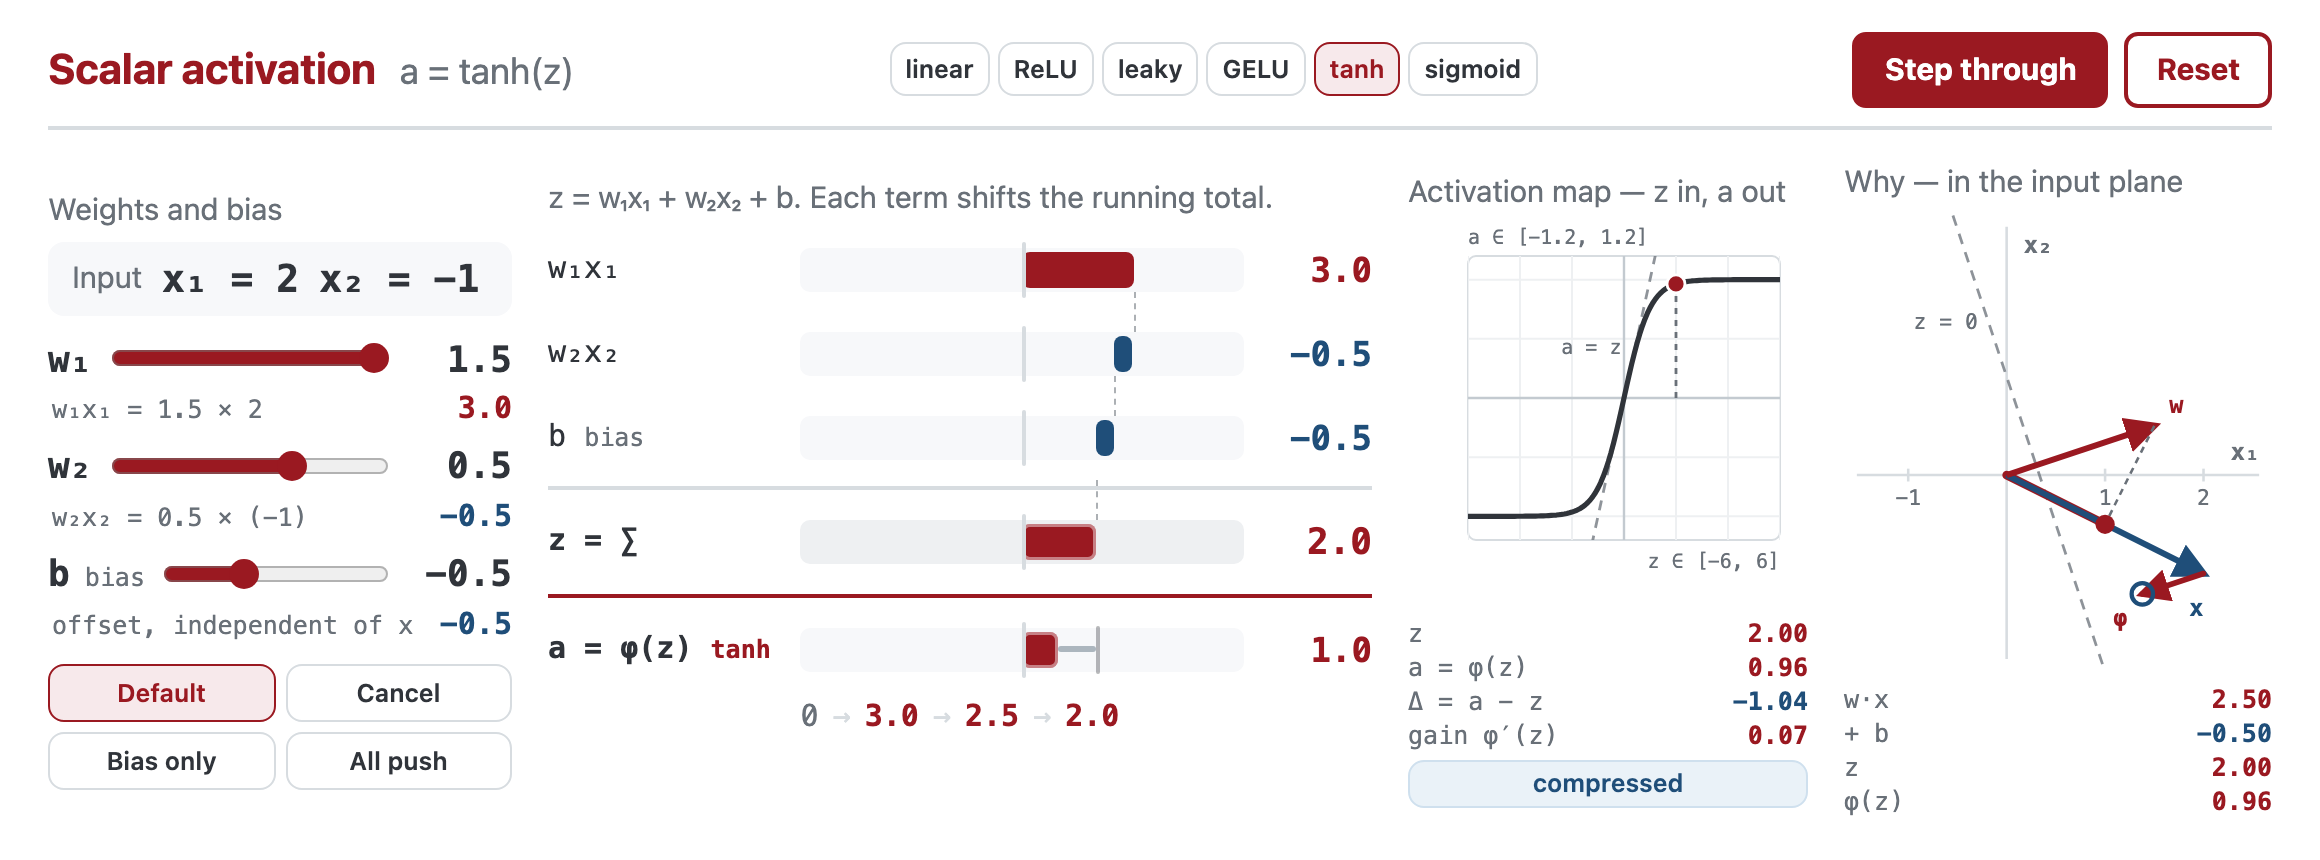 ▶ Interactive
Scalar Activation
Push the same weighted sum z through six switchable activation functions and see how a = φ(z) changes.
Knowledge point: why nonlinear activation functions matter.
Open Demo →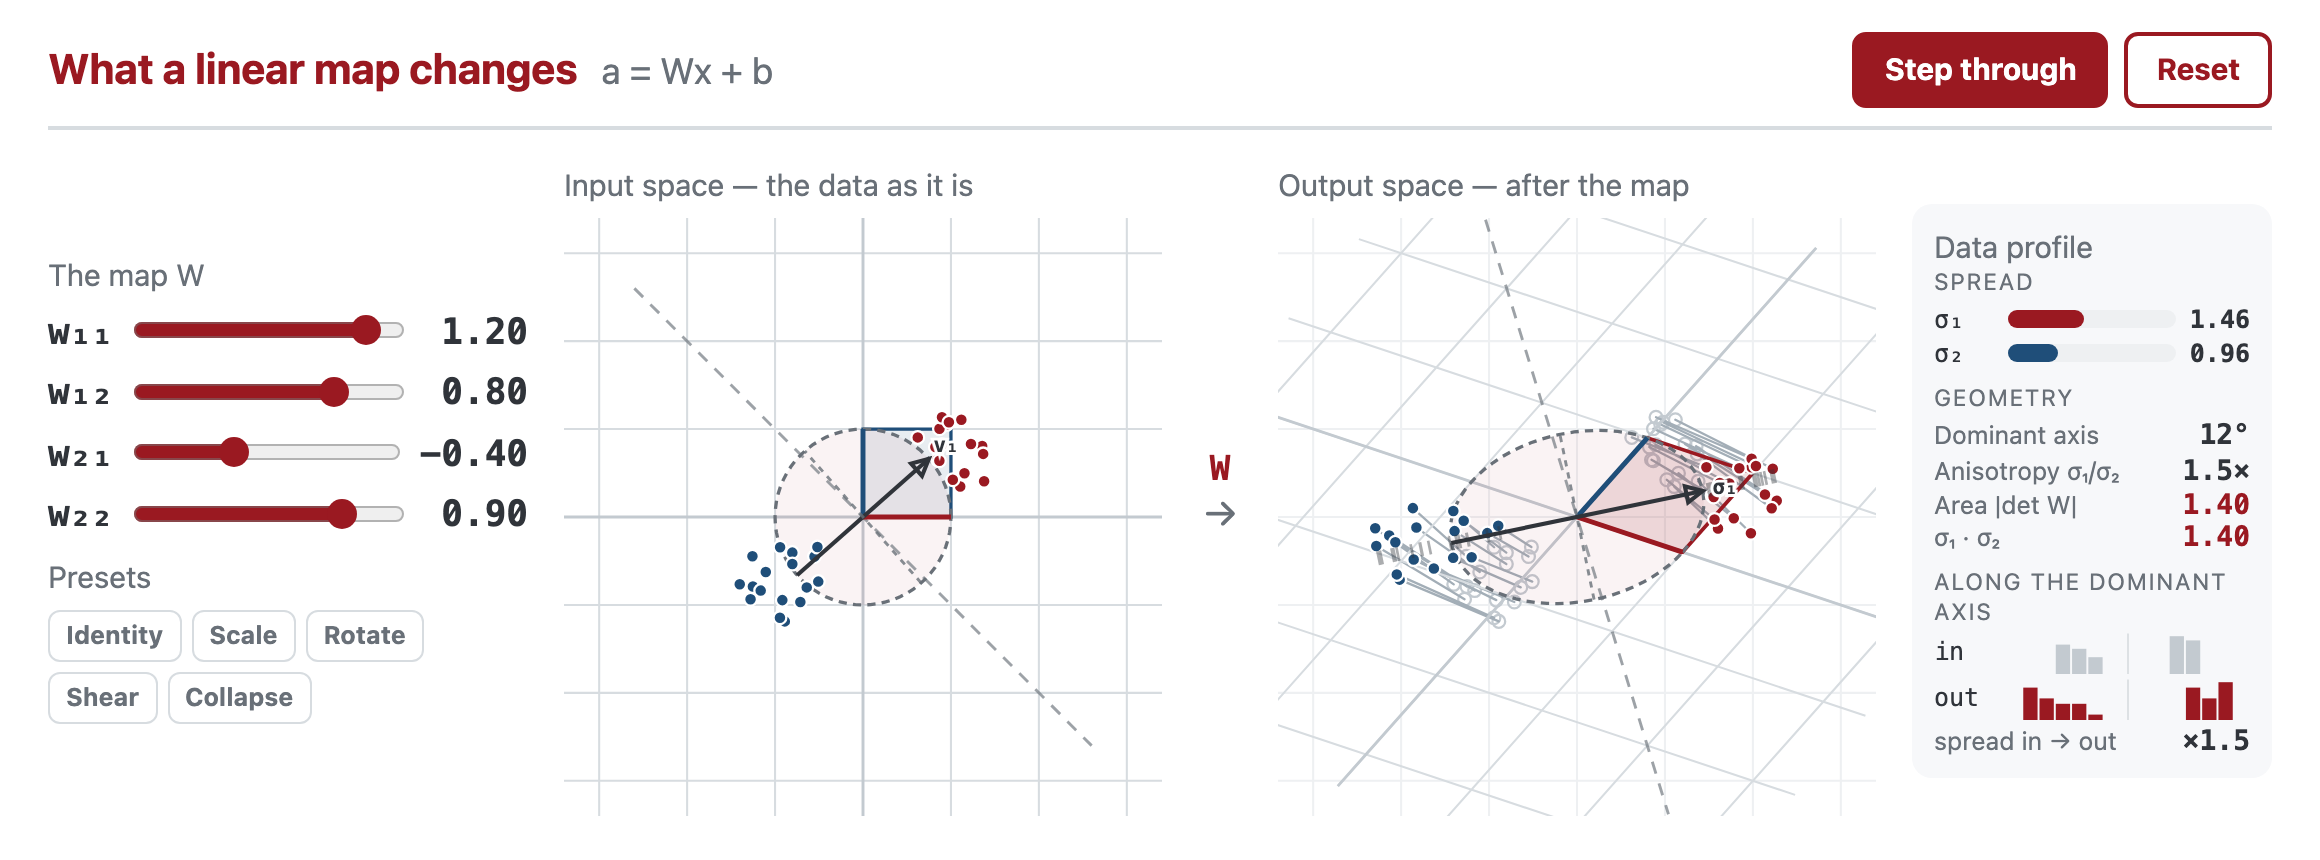 ▶ Interactive
What a Linear Map Changes
Watch a weight matrix W stretch a grid, a circle, and a point cloud, with the singular axes drawn to scale.
Knowledge point: matrices as geometric transformations of the data space.
Open Demo →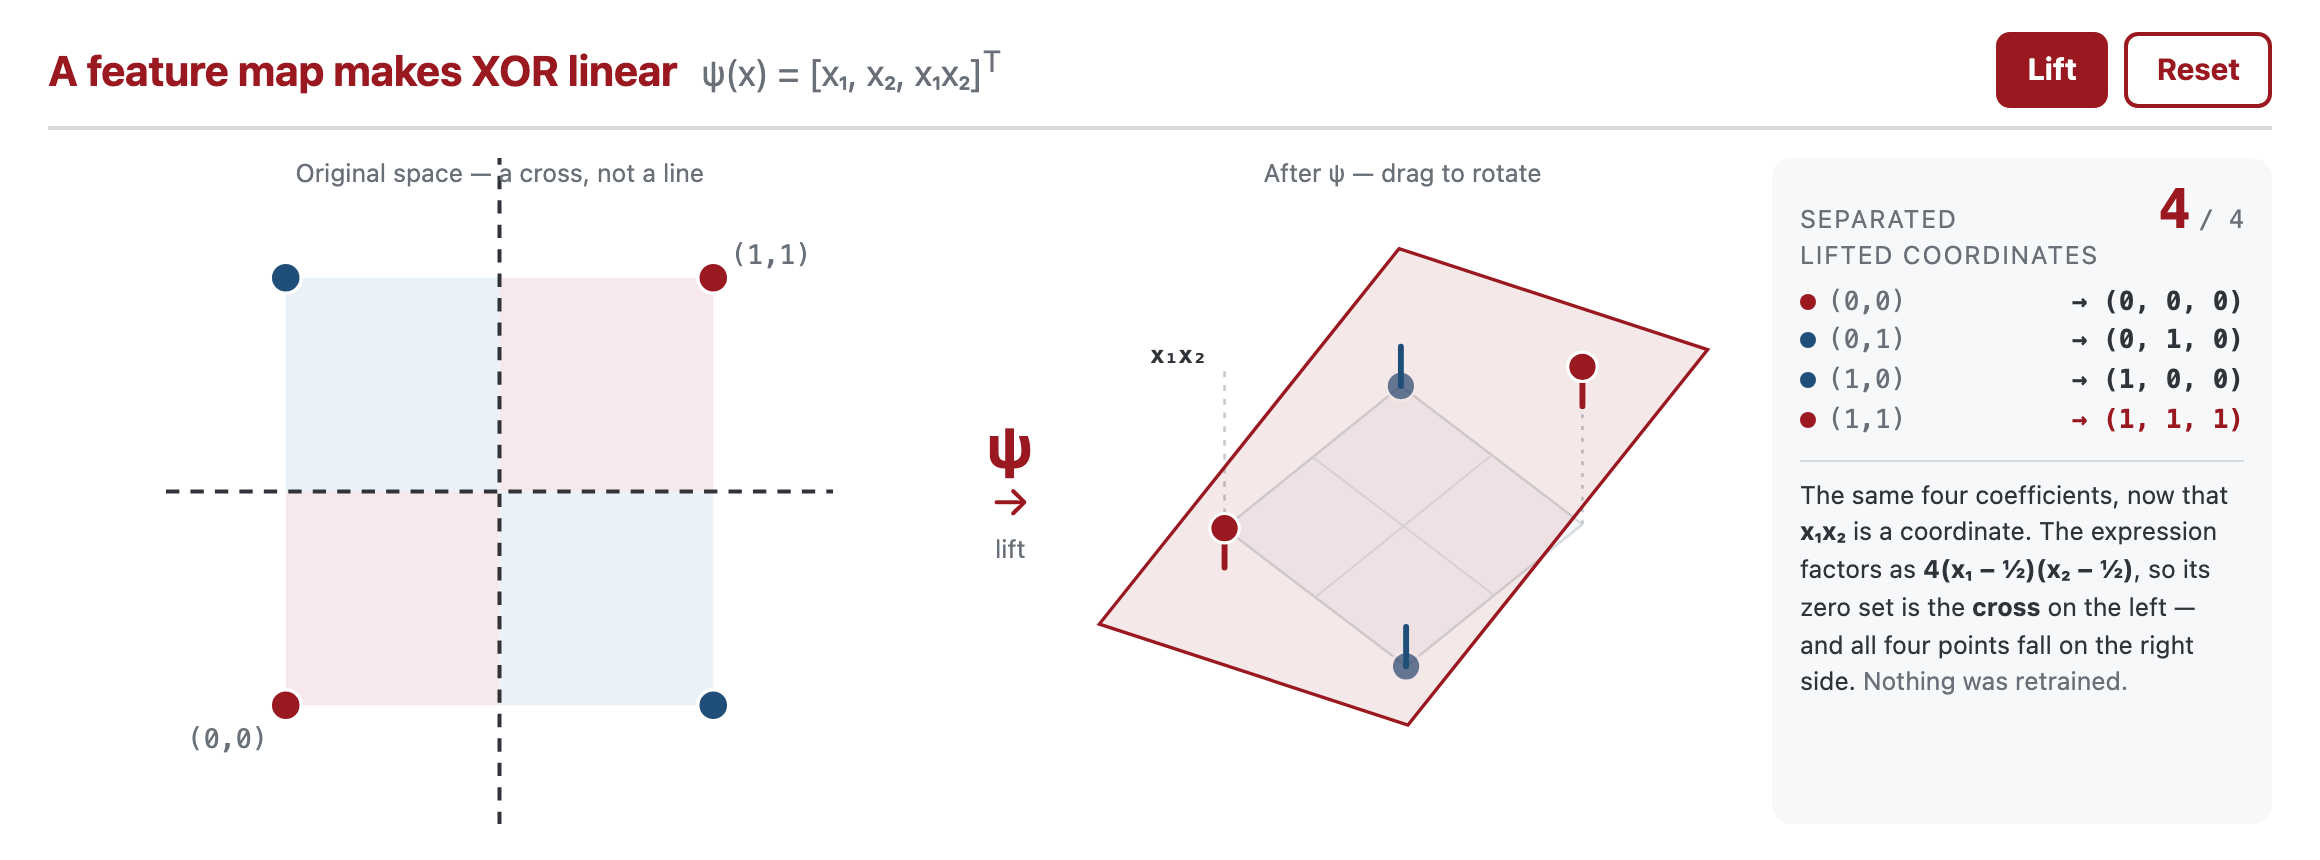 ▶ Interactive
A Feature Map Makes XOR Linear
Lift the XOR points into 3D with ψ(x) = (x₁, x₂, x₁x₂) and watch a plane separate what no line could.
Knowledge point: nonlinear feature maps and the kernel-trick intuition.
Open Demo →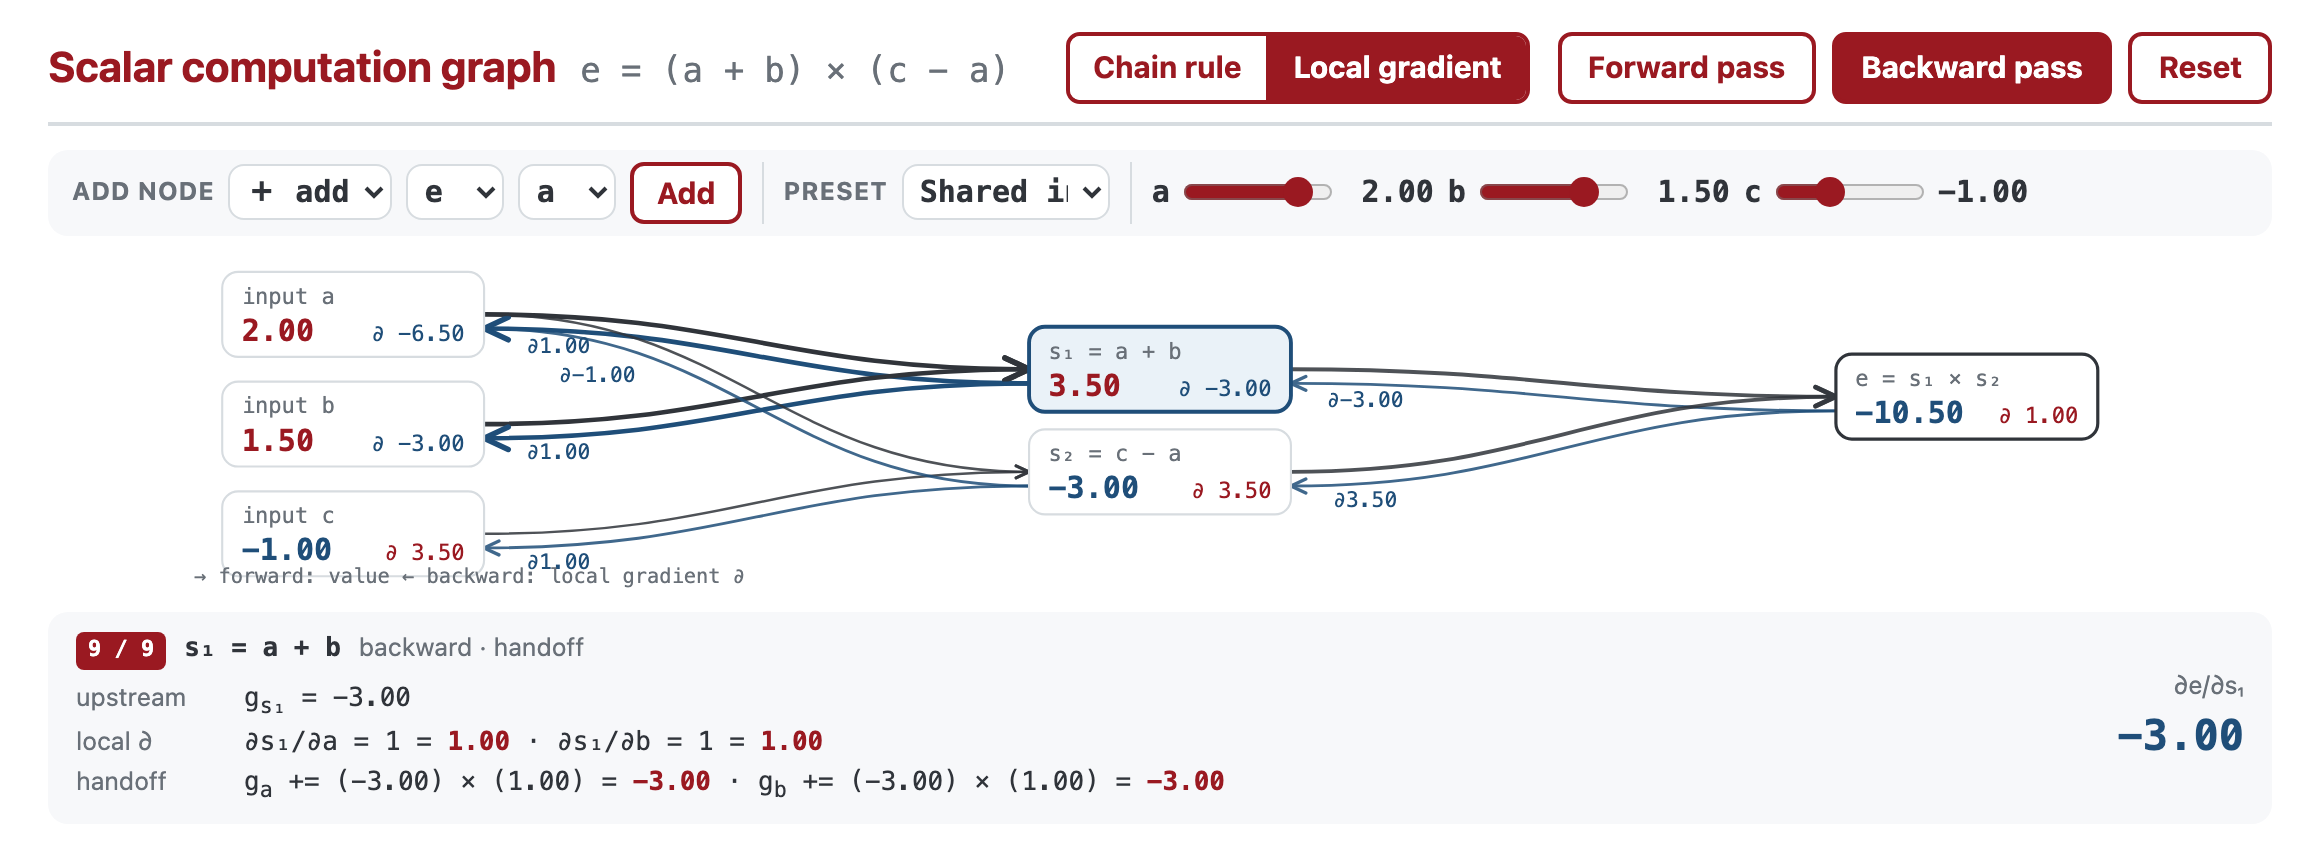 ▶ Interactive
Scalar Computation Graph
Build a graph of + − × ÷ nodes and watch values flow forward while gradients flow back, node by node.
Knowledge point: the chain rule and how automatic differentiation works.
Open Demo →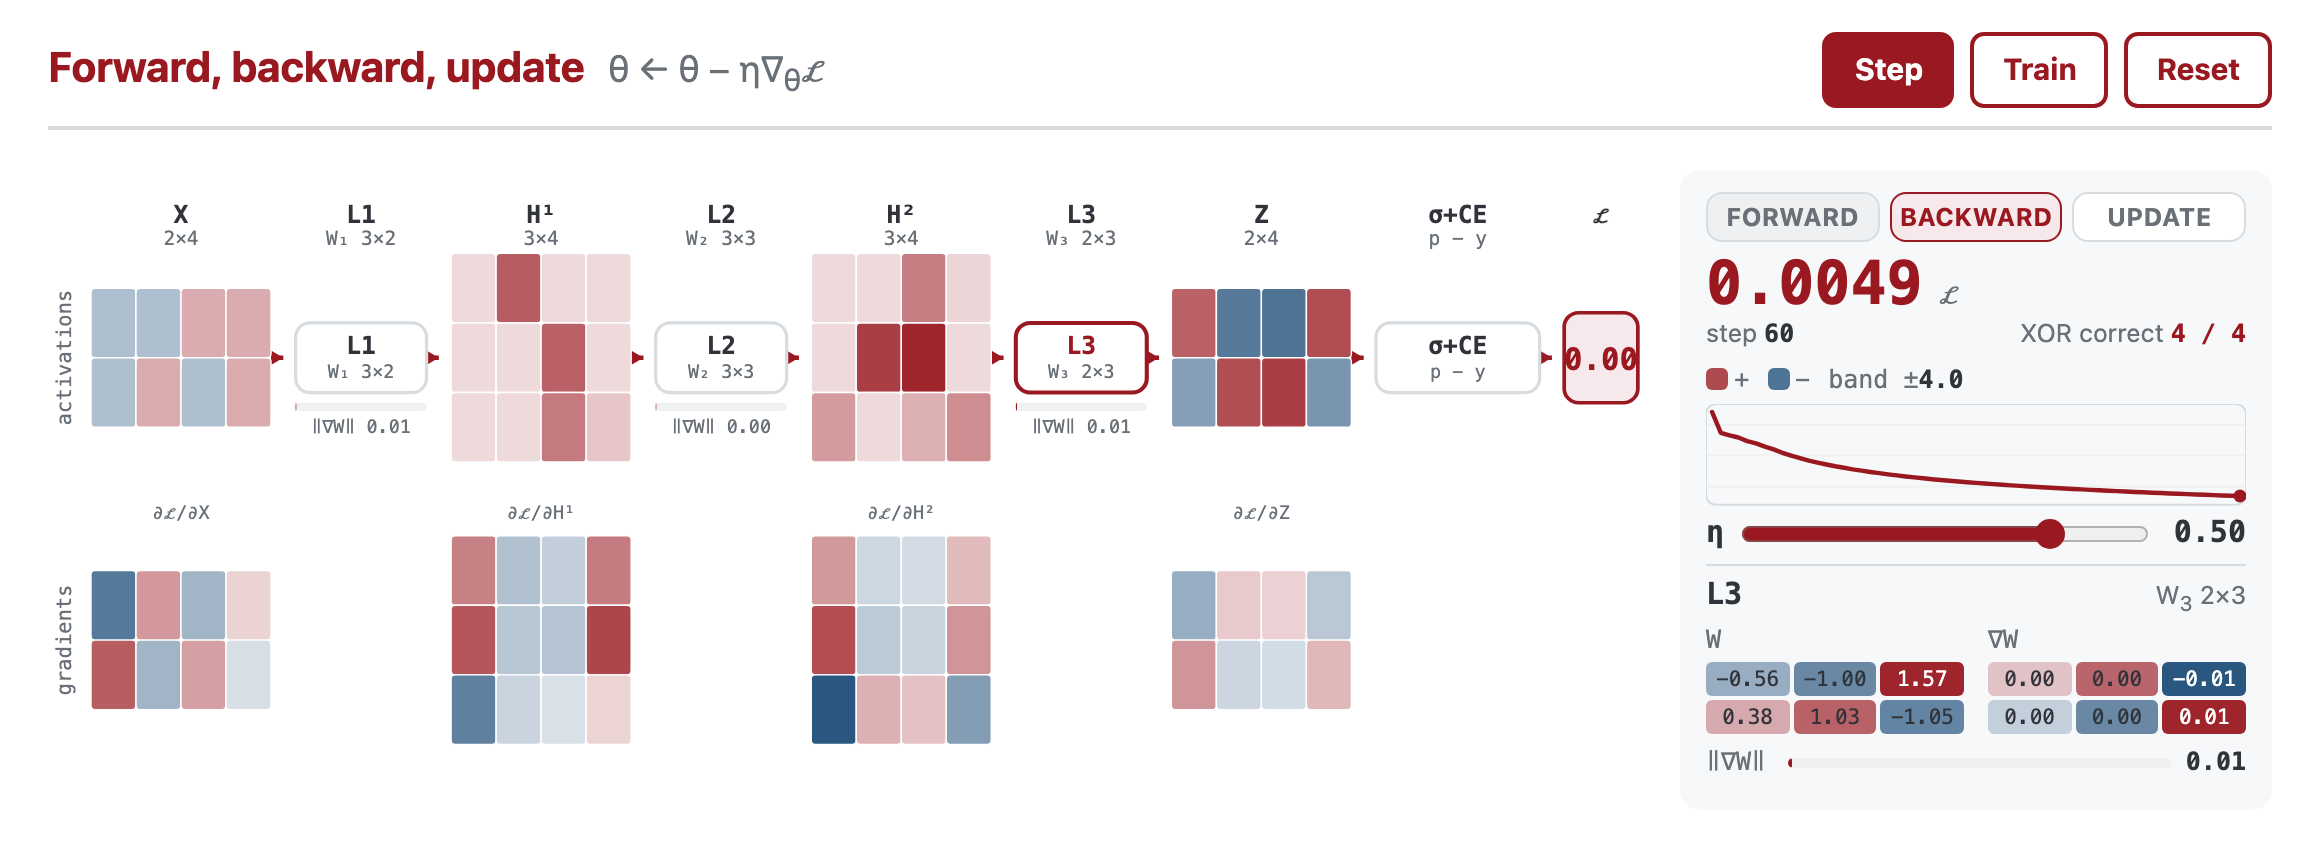 ▶ Interactive
Forward, Backward, Update
Train a small MLP on the XOR corners one phase at a time — forward activations, backward gradients, then a parameter update.
Knowledge point: the full training loop, from forward pass to gradient descent.
Open Demo →